

Webhook
The webhook node is the entry point of every workflow. It listens for incoming events and triggers the workflow when one is received. Every workflow must begin with a webhook node — it cannot be deleted or moved to a different position in the flow. When you open the webhook node, you’ll see:- Test URL — a temporary endpoint for sending test events during development. Copy this URL to use when testing.
- Production URL — the live endpoint that triggers the workflow once it’s active.
- Response type — controls when the webhook sends a response back to the caller:
- Immediate — responds to the caller as soon as the webhook is received, before the rest of the workflow runs.
- After last node — waits until the final node in the workflow completes before responding. This adds a Response node to the end of your workflow.
Input
The input node is an entry point for test runs, like the webhook is for live runs. It stores a JSON payload and starts a test run from itself, so you can test a workflow, or one branch of it, without sending a request to the webhook’s test URL each time. It only has an output handle, and live runs never start from it. Drag Input onto the canvas, connect it to the node where the test should start, paste a JSON object or array into it, and click Test. For how to use saved payloads while you build, with examples, see Build and debug faster in the editor in the Build Guide.HTTP
The HTTP node makes a call to an external API or service and passes the response downstream. Use it to query a pricing engine, send data to your ERP, or trigger actions in other tools. Configuration options:- URL — the API endpoint to call.
- Method — the HTTP method: GET, POST, PUT, DELETE, or PATCH.
- Authentication — select a pre-configured authenticator (OAuth2 or API key) to handle authentication automatically. Authenticators are configured under Administration > Authenticators.
- Headers — toggle on to add custom request headers as key/value pairs.
- Params — toggle on to add URL query parameters as key/value pairs.
- Body — toggle on to add a request body (JSON or raw text).
- Response mode — controls how the node’s response is passed to the next node:
- Replace — the HTTP response replaces the current data payload entirely.
- Append — the HTTP response is merged into the existing payload alongside previous data.
Transform
The transform node processes and modifies data as it moves through the workflow. Use it for calculations, field mapping, formatting, filtering, or any logic that needs to run between other steps. Transformation logic is written in JavaScript. The node provides a code editor where you write a function that receives the current data payload and returns a modified version. The input and output viewers show the live data state before and after transformation, making it easy to verify your logic is working correctly. Use the Test button to run the transformation against the current input data. The node’s dialog has a Logs tab for the code’sconsole output, and shows the line of a failed run’s error in the Output tab. See Transform logs and error lines in the Build Guide.
For what the code receives, what it may return and recipes for common rules, see Writing Transform code in the Build Guide.
Switch
The switch node routes data down different paths based on conditions you define. Use it to branch your workflow — for example, sending order requests one way and quote requests another. Each switch node contains one or more routes. Each route has:- Name — a label for the path (shown on the canvas connection line).
- Condition — a comparison that must be true for data to follow this route. A condition is a first value, an operator, and a second value. Drag data from the input viewer onto either value input to reference a field from the current payload, or type a literal.
- Default — one route can be marked as the default fallback, which is taken when no other conditions match.
Each route creates a separate output handle on the node. Connect each handle to the next node in that path. The switch node evaluates conditions in order and follows the first route that matches.
Every switch node should have a default route configured to handle cases where none of your conditions match.
Intent Switch
The intent switch node routes data by the request’s classified intent, with no code and no JSON. It works like the switch node, but each route lists intents instead of conditions. Use it to send orders one way and quotes another, or to give one intent its own path. Configuration options:- Route name — a label for the path, shown on the canvas connection line.
- Intents — one or more intents for the route, chosen from your organization’s intent tree. Search the tree, and select several at once.
- Fallback route — an optional route taken when no other route matches. Without one, the branch ends when no route matches.
- An intent can belong to only one route. The picker disables the intents that other routes already use.
- Pulse saves the intent ids, and shows names from the intent tree each time. If you rename an intent in Axon, the new name appears in Pulse without changing the workflow.
- An intent that has since been deleted is flagged in the route, with a way to remove it.
If the payload has no intent, the node fails instead of taking the fallback, so a data problem is visible in Executions. Add a fallback route for intents you have not planned for.
If
The if node splits a workflow into two paths based on a single condition. Use it when you only need a yes/no decision — for example, “does this order include a hazardous material?” — and want to keep the canvas simpler than a full switch node. Configuration options:- Condition name — an optional label shown on the canvas so you can tell at a glance what the node checks.
- Condition — a first value, an operator, and a second value. Drag data from the input viewer onto either value input to reference a field from the current payload, or type a literal. Uses the same operators as the switch node (equal to, contains, greater than, etc.).
- Add else branch — by default, the if node only has a then output that fires when the condition is true. Click Add else branch to also create an else output for the false path. Click Remove else branch to drop the else path — any edges connected to it are removed.
Price check
The price check node compares the captured price (the unit price extracted from the source document — PDF, Excel, email, etc.) against the ERP price (any price coming from another source, typically your ERP) for each line in the payload and decides which one becomes the final unit price. Use it to reconcile pricing discrepancies before an order is confirmed downstream. The node only rewrites lines where the two prices are close enough to be considered the same offer. Lines with a bigger gap are passed through untouched so a human can review them. Configuration options:-
Run if — an optional gate that decides whether the check runs for a given payload. Uses the same first value / operator / second value pattern as other conditions. Leave both values empty to always run. Example: skip payloads whose warnings mention mounting by setting the first value to the warnings field and using does not contain with
mounting. -
Max price deviation (%) — the check only applies when the captured and ERP unit prices differ by at most this percentage. Lines with a bigger gap are left untouched. Defaults to
5. - Price cap — lines where either unit price exceeds this amount are left untouched. Leave empty for no cap. Useful for holding back high-value lines for manual review regardless of deviation.
-
Retain — which price becomes the line’s final unit price when the check applies:
- Captured price — keep the price extracted from the document. This also marks the price as user-selected so downstream systems treat it as manually confirmed.
- ERP price — replace the captured price with the ERP price.
- Write message — when enabled, appends an explanatory line to the payload’s messages every time the check is applied, describing the retained price, the deviation, and the recalculated total. Turn on for auditability; turn off to keep messages clean.
Calculate
The calculate node works out a field from a formula over other fields, like a spreadsheet cell. Use it to keep dependent values right when a user edits a request in Flow. For example, recalculate a line’s total price when its quantity changes, apply a header discount to every line, or add up the lines into an order total. No code is needed. The node is only available in On Field Update workflows. See On Field Update for when these workflows run.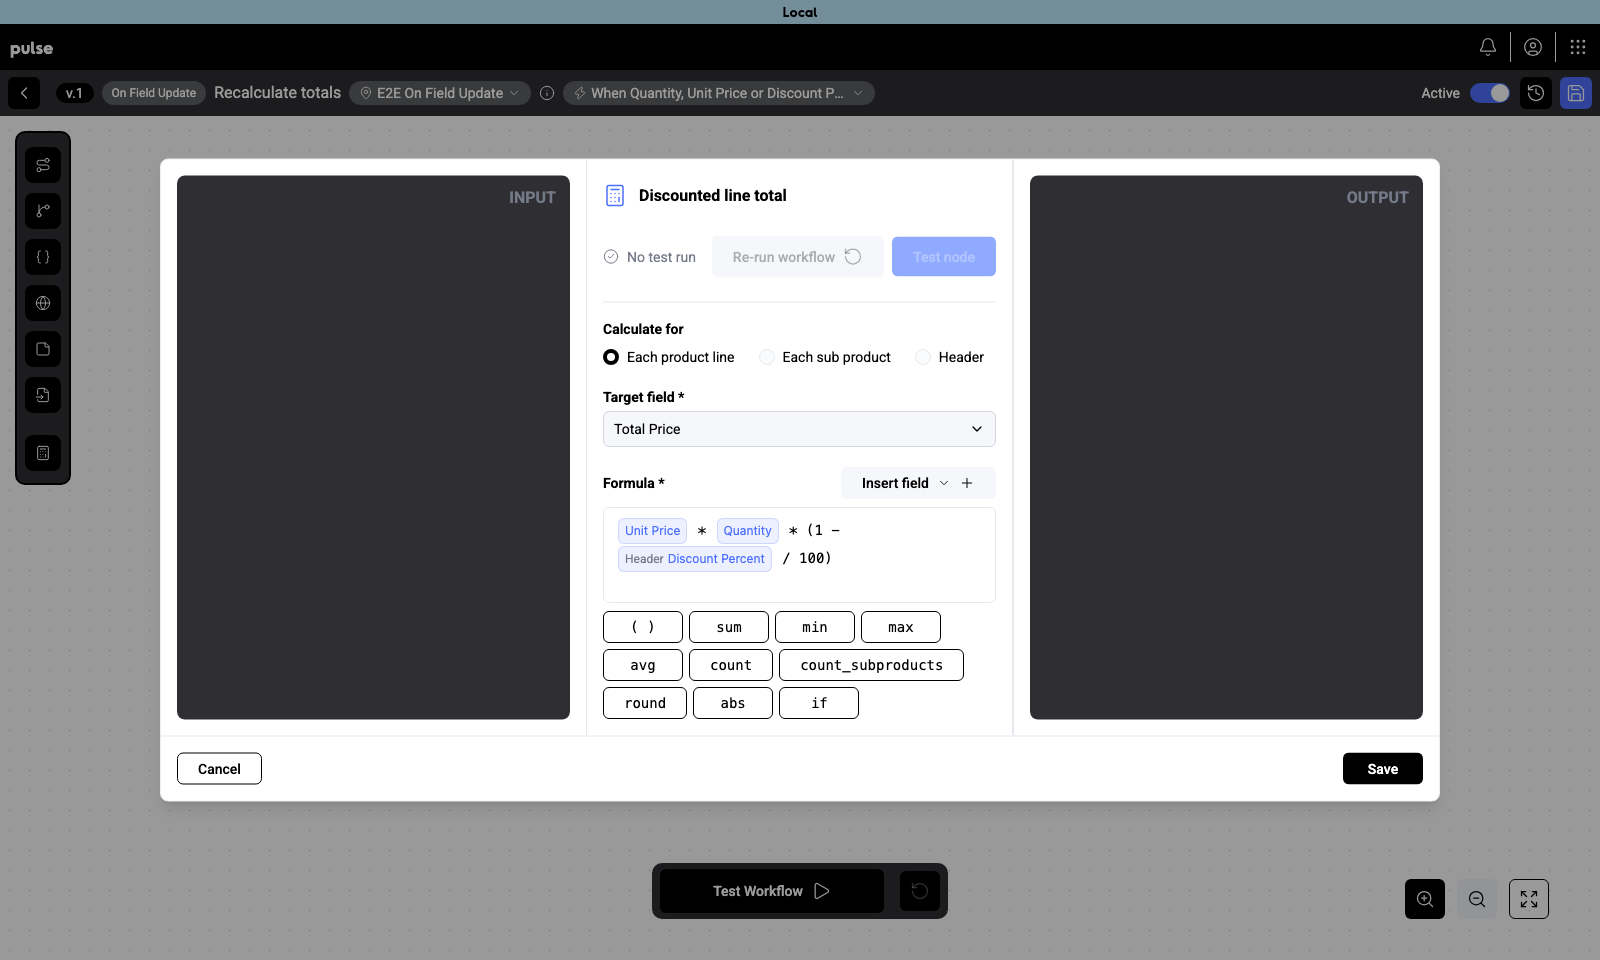
A Calculate node that applies the header discount to each line's total price
- Calculate for: where the formula runs and where the result is written.
- Each product line: once per product line. The result goes into a product line field.
- Each sub product: once per sub product of every line. The result goes into a sub product field. Lines without sub products are left alone.
- Header: once for the whole request. The result goes into a header field.
- Target field: the field that receives the result. The list shows the fields of the matching level (product line, sub product or header).
- Formula: the calculation. Click Insert field to add a field, or type it in square brackets. Fields show as pills with their display name. Click a function button below the formula to add it, and hover a button to see examples.
- Decimals: how many decimals the result is rounded to, from 0 to 10. With 2 decimals, 67.5 is written as
67.50. - Only recalculate changed lines: for Each product line and Each sub product. When on, only the lines the user changed are recalculated (with every sub product of those lines). A change to a header field still recalculates every line.
Use
+ - * / and parentheses for arithmetic, and > < >= <= == != for comparisons. The functions are:
A few rules to keep in mind:
- An empty or missing field counts as 0. Values such as
1.234,56,1,234.56andEUR 12.50are read as numbers. In the formula itself, use.as the decimal separator. - Sub products that are not selected (alternatives nobody picked) are left out of sums, averages and counts.
- A Header formula can only read product lines inside
sum,avg,minormax, and can’t read sub products. To use sub products in the header, first add them up into a product line field, then add up the lines. - If a line can’t be calculated, for example because of a division by zero, its target field is left as it was and a warning is added. The other lines are still calculated.
- Each product line, target Total price:
[unit_price] * [quantity] * (1 - [header.discount_percent] / 100) - Header, target Order total:
sum([line.total_price]) + [header.freight]
if() in the formula only for a condition that differs per line, such as the line’s quantity.
Use Test node to run the node against its input and check the result before saving.
Sticky note
The sticky note is a canvas annotation, not an executable step. Use it to leave context on a workflow — a reminder about why a branch exists, a TODO for a teammate, or a section header that groups related nodes. Sticky notes are ignored at runtime and never appear in execution logs. Drag Sticky note from the node inventory onto the canvas to add one. Double-click a sticky note (or click Edit in its toolbar) to open the full editor, where a larger textarea makes it easy to write longer notes. Configuration options:- Text — the note’s content. Type directly on the canvas for short notes; open the editor for longer ones. Text that overflows the visible area on the canvas is clipped with a subtle fade — the full content is always visible in the editor.
- Color — pick from yellow, pink, green, or blue using the swatches in the node’s floating toolbar or in the editor. Use color to distinguish note types at a glance (e.g., yellow for reminders, pink for warnings).
- Size — drag the corner handles when the note is selected to resize it. Sticky notes have a fixed minimum and maximum size; text past the maximum is clipped on the canvas but preserved in the editor.
Return
The return node ends a workflow path and sets the answer Pulse sends back to request processing for the workflow’s stage. The options in the node’s Return dropdown depend on the stage. For which stage to build at, and what each one is for, see Stages and what each one returns in the Build Guide. Gate stages (Can Classify and Can Extract) answer whether processing should continue:
Output stages (On Classification, On Extraction, On Account Resolution, and On Transformation) return data:
In the On Account Resolution stage, return the candidate accounts with Custom JSON. Returning the input unchanged resolves no account. For example: